Most marketing teams do not have an ideas problem. They have a decision problem.
SEO has a list of content, technical and SERP opportunities. Paid media wants new audiences, offers and landing pages. CRM wants lifecycle improvements. Product has activation friction. Meanwhile, leadership wants growth, but nobody can confidently explain which proposed test deserves capacity first, what would count as success, or how a successful result becomes standard practice.
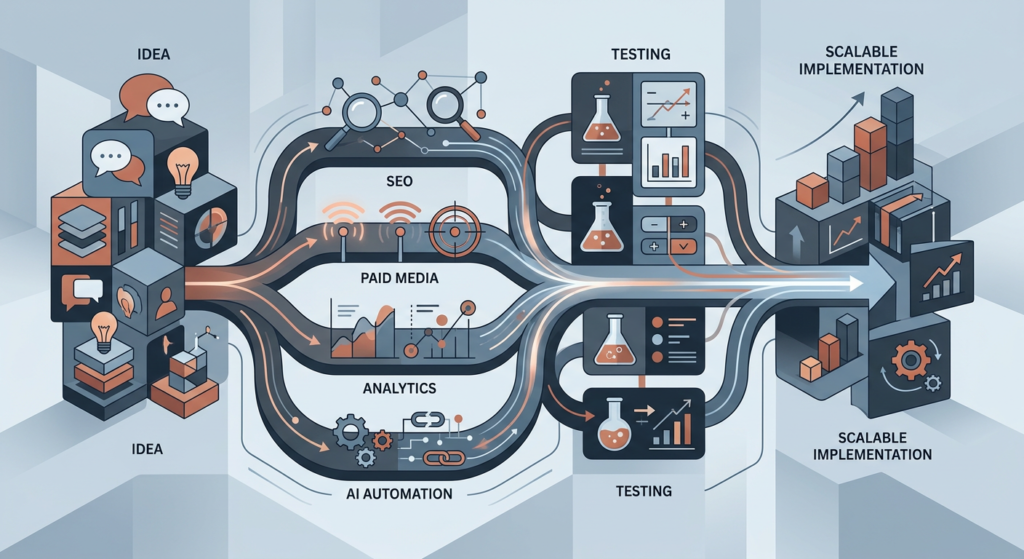
A marketing experimentation framework solves this by creating an operating system, not merely a test tracker. It gives teams one intake process, a shared method for prioritising work, an agreed measurement plan and a route from isolated learning to repeatable action.
The goal is not to run the greatest possible number of tests. It is to make better growth decisions with finite traffic, budget, engineering time and attention.
Start with the business constraint, not a channel backlog
Experiments should be answers to a current constraint. If qualified pipeline is weak, improving a low-intent blog click-through rate may be interesting but not urgent. If paid acquisition is becoming less efficient, another landing-page variant may matter more than expanding targeting.
Begin each planning cycle by identifying one primary constraint: insufficient demand, poor conversion, low lead quality, slow activation, weak retention, limited capacity or unreliable measurement. Then connect it to the commercial metric it affects.
A marketing KPI tree is useful here because it separates the outcome leaders care about from the channel metrics teams can influence. This prevents the common mistake of treating a movement in impressions, clicks or engagement as a business result by default.
Operational recommendation: set one quarterly experimentation theme for each growth team, such as “increase sales-qualified lead rate” or “reduce first-purchase friction.” Keep room for urgent defects, but do not let the urgent queue become the entire programme.
Create one cross-channel experimentation backlog
A single backlog does not mean every team loses specialist judgement. It means all proposed changes are visible and comparable before they consume scarce resources. A spreadsheet works initially; a project-management tool is useful once volume and dependencies increase.
Every entry needs enough detail to support a decision. Require these fields:
- Opportunity: the observed problem, segment or behaviour.
- Channel and journey stage: for example, organic discovery, paid consideration, lead capture or onboarding.
- Proposed intervention: the change being considered.
- Hypothesis: the expected mechanism and measurable outcome.
- Primary metric: the metric used to judge the intended effect.
- Guardrails: metrics that must not deteriorate beyond an agreed tolerance.
- Audience, pages or markets: the eligible test population.
- Effort, dependencies and risk: including analytics, legal, product and engineering needs.
- Owner and decision date: one accountable person and a defined review point.
Sources for ideas should be broad: search-query analysis, CRM loss reasons, sales calls, support tickets, funnel drop-off, competitive reviews, customer research, analytics anomalies and post-campaign reviews. A search-led customer insight system can supply particularly useful language and intent patterns for SEO, answer engine optimisation and landing-page experiments.
Operational recommendation: separate observations from solutions in the backlog. “Visitors abandon the pricing page after viewing implementation details” is an observation. “Add a comparison table” is one possible solution. This distinction stops the first idea from becoming the only idea.
Write hypotheses that can be disproved
A good hypothesis states who will experience what change, why it may work and how the team will assess it. It is not a promise of growth.
Use this structure: For [defined audience], changing [specific element] from [current state] to [proposed state] will improve [primary metric] because [evidence-based mechanism], without materially harming [guardrail metrics].
For an SEO test, that could be: “For non-brand visitors landing on commercial service pages, adding concise decision criteria and source-supported answers near the top of the page will increase qualified enquiry rate because it reduces uncertainty for comparison-stage users, without reducing organic traffic or increasing unqualified submissions.”
Notice what this does not claim. It does not assume rankings will rise. Search outcomes are influenced by variables that are difficult to isolate, and page changes can affect relevance, conversion and crawl behaviour differently.
Source note: Google’s Search documentation is a reference point for technical implementation and search appearance eligibility. It should be used to check constraints, not as evidence that a specific optimisation will produce a ranking or traffic outcome.
Score ideas consistently, then apply judgement
Prioritisation models are imperfect, but a transparent imperfect model is better than a loudest-voice model. I favour a modified RICE score because it combines opportunity with practical feasibility.
| Factor | Question | Suggested scale |
|---|---|---|
| Reach | How many relevant users could encounter the change in the test period? | 1–5 |
| Impact | If the hypothesis is right, how meaningful is the effect on the current constraint? | 1–5 |
| Confidence | How strong is the evidence from data, research or prior tests? | 1–5 |
| Effort | How much combined delivery, review and analysis work is required? | 1–5 |
| Risk | Could the change damage compliance, user trust, tracking or a critical journey? | 1–5 |
A simple formula is: (Reach × Impact × Confidence) ÷ (Effort × Risk). Use the result to order discussion, not to automate it. A low-scoring tracking repair may be mandatory because all subsequent conclusions depend on it. A high-scoring test might wait because the team cannot obtain a clean comparison group.
Operational recommendation: score proposed work in a weekly or fortnightly triage session with channel, analytics and delivery representatives. Record why exceptions were made. That record is valuable when someone later asks why a seemingly attractive test was deferred.
Set primary metrics and guardrails before launch
Every experiment needs one primary success metric. More than one primary metric usually creates room to select a flattering result after the fact. Supporting metrics can help explain the outcome, but they should not rewrite the decision rule.
Guardrails protect the wider system. For a paid-media landing-page test, they may include cost per qualified lead, form error rate and lead acceptance rate. For an answer engine optimisation test, they may include organic clicks, branded-query mix, conversion quality and factual accuracy. For an AI-assisted workflow, they may include human correction rate, turnaround time and policy exceptions.
Measurement quality is a prerequisite, not an afterthought. If CRM stage definitions, consent handling or campaign identifiers are inconsistent, a channel can appear to improve while lead quality is simply being recorded differently. Establishing a marketing data contract makes the required fields, owners and system definitions explicit.
Operational recommendation: define in advance the minimum observation period, the decision threshold and the stopping conditions. Stop early for clear technical failure or unacceptable guardrail harm; do not stop merely because a short-term result is exciting.
Use a test brief that makes ownership unambiguous
A backlog item becomes an active experiment only when it has a short, approved brief. This is where many programmes break down: everyone contributes, but nobody is accountable for the decision.
Assign four distinct roles. The experiment owner is accountable for the brief and final recommendation. The delivery owner implements the change. The measurement owner validates instrumentation and analysis. The approver resolves material risk or resource trade-offs. One person can hold more than one role in a small team, but the responsibilities should still be named.
Operational recommendation: do not start until the owner can answer five questions in writing: What changes? For whom? What metric decides the outcome? What could make the result misleading? What happens under each possible outcome?
Illustrative scenario: improving lead quality, not just form volume
A B2B team sees a healthy volume of paid-search form submissions but poor sales acceptance. Its first instinct is to reduce cost per lead. The operating system reframes the constraint: low-quality demand is the problem, not lead quantity.
The team prioritises a test that adds role, company-size and timeline context to the form and adjusts ad copy to qualify the offer. Primary metric: sales-accepted lead rate. Guardrails: completed-form rate, cost per sales-accepted lead and sales follow-up time. The result may reduce submissions while improving commercial quality. That is not a failed test if the pre-agreed decision metric improves.
Run an operating cadence, not a collection of launches
A durable programme has recurring meetings with different purposes. Keep them brief and evidence-led.
- Weekly triage: add, refine and score ideas; remove duplicates and weak proposals.
- Weekly delivery check: review blockers, QA, audience exposure and tracking health for live work.
- Monthly readout: decide to scale, iterate, stop or archive completed tests.
- Quarterly portfolio review: assess which themes, channels and capabilities are producing transferable learning.
Do not confuse activity reporting with a readout. A readout should include the hypothesis, implementation, exposure, observed result, guardrail status, limitations, decision and next action. If a test is inconclusive, say so. Inconclusive is useful when it prevents a team from scaling an unproven change.
Source note: Bing’s Webmaster resources can inform technical checks for search-focused changes. They do not replace first-party measurement of audience response and commercial outcomes.
Turn wins into standards, not slide decks
The highest-value part of experimentation happens after the result. A positive outcome in one campaign, template or market is not automatically a universal rule. It may depend on traffic source, device, offer, audience maturity or implementation quality.
Classify completed work into four states: scale, iterate, stop and monitor. Scaling means defining where the change should be repeated, who will deploy it, what QA is required and what metric confirms that the benefit holds outside the original test. Iteration means documenting what was learned and identifying the next uncertainty.
Maintain a decision log and a reusable playbook library. For each scalable pattern, capture the eligible context, excluded context, implementation specification, evidence strength, expected trade-offs and review date. This is how an agency or in-house team avoids rediscovering the same lesson across accounts or business units.
FAQ and conclusion
How many experiments should a team run at once?
Run only as many as you can instrument, deliver and analyse properly. Small teams often learn faster from one or two well-governed tests than from a crowded backlog of partially measured launches. Avoid overlapping tests that change the same audience or journey unless you can interpret their combined effects.
What if SEO tests cannot be cleanly A/B tested?
Use the strongest practical comparison available: matched page groups, phased rollouts, pre-defined time windows or regional splits. Document confounders such as seasonality, site releases and demand changes. Treat conclusions as directional when isolation is weak rather than presenting correlation as proof.
Who should own the experimentation programme?
One growth or marketing operations lead should own the system and cadence. Channel specialists should own hypotheses in their domain, while analytics owns measurement standards. Senior leadership should resolve priorities, not approve every small test.
A useful marketing experimentation framework makes learning operational. Anchor tests to a real constraint, use explicit hypotheses and guardrails, assign accountable owners, and record decisions with enough context to reuse them. The result is not certainty. It is a disciplined way to place better bets, stop weaker ones sooner and scale only what your evidence supports.